 |
|
Predicting genomic biomarkers directly from digitized histopathology whole-slide images offers a cost-effective and scalable alternative to traditional molecular assays. However, the field faces a structural bottleneck: every time a new genomic biomarker is discovered or quantified, researchers must prospectively collect large, labeled datasets to train new predictive models.
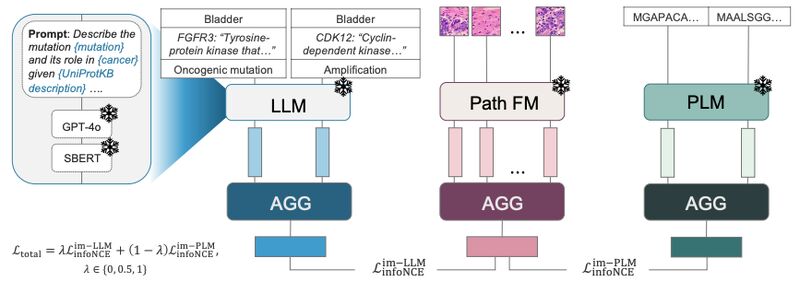
A new paper by 𝙀𝙠𝙖𝙩𝙚𝙧𝙞𝙣𝙖 𝙍𝙚𝙙𝙚𝙠𝙤𝙥 𝙚𝙩 𝙖𝙡. addresses this challenge with 𝙈𝘼𝙍𝘽𝙇𝙀, a multimodal contrastive pretraining strategy.
Here are the key innovations
from the research:
• 𝘽𝙞𝙤𝙡𝙤𝙜𝙞𝙘𝙖𝙡𝙡𝙮 𝙄𝙣𝙛𝙤𝙧𝙢𝙚𝙙 𝘼𝙡𝙞𝙜𝙣𝙢𝙚𝙣𝙩: Instead of relying solely on visual data, 𝙈𝘼𝙍𝘽𝙇𝙀 integrates structured biomarker knowledge directly into the representation learning of histopathology images.
• 𝙇𝙇𝙈𝙨 𝘼𝙣𝙙 𝙋𝙇𝙈𝙨 𝘼𝙨 𝘼𝙣𝙘𝙝𝙤𝙧𝙨: The framework functions by aligning representations derived from histopathology images with representations of genomic biomarkers that are generated by a large language model (LLM) and a protein language model (PLM).
•
𝙊𝙪𝙩-𝙊𝙛-𝘿𝙞𝙨𝙩𝙧𝙞𝙗𝙪𝙩𝙞𝙤𝙣 𝙂𝙚𝙣𝙚𝙧𝙖𝙡𝙞𝙯𝙖𝙩𝙞𝙤𝙣: By grounding the visual data in biological semantics, this alignment enables data-efficient generalization to novel, out-of-distribution biomarkers without requiring massive new training datasets.
• 𝙍𝙚𝙖𝙡-𝙒𝙤𝙧𝙡𝙙 𝙑𝙖𝙡𝙞𝙙𝙖𝙩𝙞𝙤𝙣: The team validated their approach using the MSK-IMPACT cohort, grounding their experiments in real-world data across over 40,000 patients and multiple biomarker panel versions.
𝙏𝙝𝙚 𝙏𝙖𝙠𝙚𝙖𝙬𝙖𝙮: As precision oncology expands, relying on building new models from scratch for every new biomarker is inefficient. By leveraging language and protein models for multimodal alignment, we can create adaptable pathology AI capable of generalizing to future discoveries.
|
|
|
|
|
|
 |
Unbottlenecking the MIL Pipeline: Four Approaches to Whole Slide AI
Extracting rich features from a pathology slide is only the first step. The real challenge is aggregating tens of thousands of isolated tile embeddings into a single, accurate clinical result.
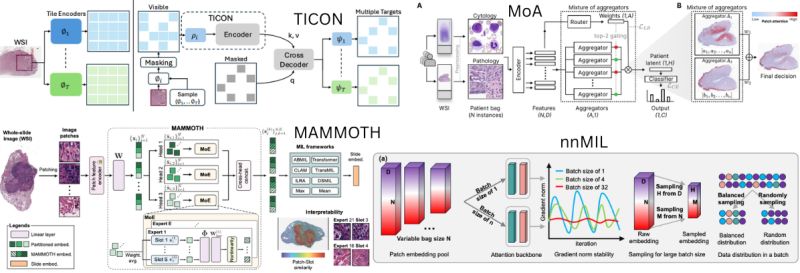
Multiple Instance Learning (MIL) is the standard framework for this task, but traditional MIL pipelines suffer from rigid linear transformations, loss of spatial context, and overly simplistic attention-pooling mechanisms. Four new papers demonstrate that instead of simply building larger patch-level foundation models, we need to completely redesign how those patches are contextualized, transformed, and aggregated.
Here is how their approaches to solving the MIL bottleneck compare:
• 𝙏𝙝𝙚 𝙈𝙞𝙭𝙩𝙪𝙧𝙚-𝙊𝙛-𝙀𝙭𝙥𝙚𝙧𝙩𝙨 𝘼𝙥𝙥𝙧𝙤𝙖𝙘𝙝: Two papers adapt the MoE paradigm to solve different bottlenecks in the MIL pipeline. 𝙈𝘼𝙈𝙈𝙊𝙏𝙃 focuses on the linear layer that transforms general features into task-specific ones 𝙗𝙚𝙛𝙤𝙧𝙚 aggregation. Using a parameter-efficient mixture of mini-experts, it applies tailored low-rank transformations to each patch's phenotype. Conversely, 𝙈𝙤𝘼 (Mixture of Aggregators) applies MoE directly to the aggregation stage. Instead of a single pooling mechanism, a router dynamically selects the top-2 most relevant aggregators for each specific slide to better capture morphological heterogeneity.
• 𝘾𝙤𝙣𝙩𝙚𝙭𝙩𝙪𝙖𝙡𝙞𝙯𝙖𝙩𝙞𝙤𝙣 𝘽𝙚𝙛𝙤𝙧𝙚 𝘼𝙜𝙜𝙧𝙚𝙜𝙖𝙩𝙞𝙤𝙣: Standard MIL treats tiles as isolated bags of features. 𝙏𝙄𝘾𝙊𝙉 is a transformer-based tile contextualizer that uses a masked modeling objective to infuse local tiles with global slide context before they ever reach the aggregator. An aggregator trained on TICON embeddings using just 11K WSIs successfully outperformed slide-level models pretrained on up to 350K WSIs.
• 𝙂𝙚𝙣𝙚𝙧𝙖𝙡𝙞𝙯𝙖𝙗𝙡𝙚 𝙎𝙖𝙢𝙥𝙡𝙞𝙣𝙜 𝘼𝙣𝙙
𝙀𝙣𝙨𝙚𝙢𝙗𝙡𝙞𝙣𝙜: While the other papers focus on specialized architectural modules, nnMIL focuses on robust training dynamics. It introduces random sampling at both the patch and feature levels to enable large-batch optimization. This is paired with a lightweight aggregator that performs sliding-window inference for ensemble slide-level predictions.
𝙏𝙝𝙚 𝙏𝙖𝙠𝙚𝙖𝙬𝙖𝙮: The next leap in computational pathology relies on the connective tissue of the MIL pipeline. Whether through contextual transformers, dynamic expert routing, or smarter sampling, overcoming the aggregation bottleneck is the key to unlocking the full potential of pathology foundation models.
MoA: Mixture of Aggregators Improves Slide-Level Diagnosis in Computational Pathology
TICON: A Slide-Level Tile Contextualizer for Histopathology Representation Learning
Mixture of Mini Experts: Overcoming the Linear Layer Bottleneck in Multiple Instance Learning
nnMIL: A generalizable multiple instance learning framework for computational pathology
|
|
|
|
|
|
 |
Running advanced AI models on smart edge devices presents a core dilemma. Users expect versatile, multi-task experiences, but these devices are fundamentally constrained by limited compute power.
To bridge this gap, we need vision encoders that are incredibly small yet capable of outputting powerful, versatile representations. Historically, researchers have tried agglomerative methods—taking multiple large, domain-expert foundation models and distilling them directly down into a single, small encoder. However, this direct scale-down struggles to efficiently capture the full breadth of knowledge required for diverse downstream tasks.
A new paper by 𝘾𝙝𝙚𝙣𝙘𝙝𝙚𝙣 𝙕𝙝𝙪 𝙚𝙩 𝙖𝙡. introduces a more effective solution: the Efficient Universal Perception Encoder (EUPE).
Here are the key innovations from their research:
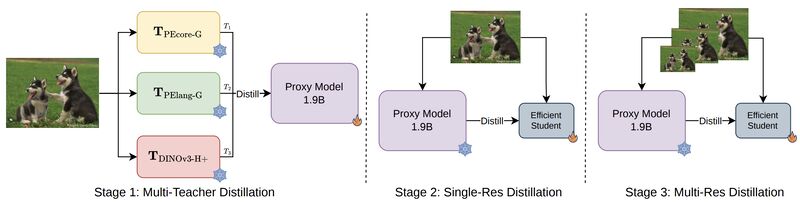
• 𝙏𝙝𝙚 𝙎𝙘𝙖𝙡𝙚-𝙐𝙥 𝘼𝙣𝙙 𝙎𝙘𝙖𝙡𝙚-𝘿𝙤𝙬𝙣 𝙎𝙩𝙧𝙖𝙩𝙚𝙜𝙮: Instead of distilling directly from multiple teachers into a small model, the authors add a crucial intermediate step. They demonstrate the importance of first scaling up by distilling multiple domain-expert models into one massive proxy teacher. Only then do they scale down, distilling from this single proxy into the efficient edge encoder.
• 𝙐𝙣𝙘𝙤𝙢𝙥𝙧𝙤𝙢𝙞𝙨𝙞𝙣𝙜 𝙋𝙚𝙧𝙛𝙤𝙧𝙢𝙖𝙣𝙘𝙚: This unique distillation process yields significantly more versatile representations. EUPE achieves on-par or
better performance across diverse task domains compared to individual domain experts of the exact same size, and it successfully outperforms previous agglomerative encoders.
𝙏𝙝𝙚 𝙋𝙤𝙩𝙚𝙣𝙩𝙞𝙖𝙡 𝙁𝙤𝙧 𝙋𝙖𝙩𝙝𝙤𝙡𝙤𝙜𝙮: While the authors focus on general smart edge devices, applying this universal, compute-efficient framework to digital pathology presents a massive opportunity. Processing gigapixel tissue slides currently relies on massive foundation models that require energy-intensive, cloud-based GPUs. The EUPE strategy could enable the field to combine and distill multiple top-tier models—such as Virchow v2, UNI2, and H-Optimus—into a massive proxy, and then scale it down into a much smaller, yet incredibly powerful model.
𝙏𝙝𝙚 𝙏𝙖𝙠𝙚𝙖𝙬𝙖𝙮: We do not necessarily have to choose between versatility and efficiency on the edge. By rethinking the distillation pipeline and
using an intermediate proxy teacher, we can deploy highly capable perception models on compute-constrained devices—potentially unlocking powerful AI everywhere from our pockets to remote pathology clinics.
|
|
|
|
|
|
 |
Cracks in the Foundation: How Data-Hungry and Sensitive to Domain Shift are Vision Foundation Models for Computational Pathology?
Vision Foundation Models (VFMs) are widely touted as the ultimate solution to data scarcity and poor generalization in computational pathology. But when stress-tested against real-world clinical variables, are they actually as robust and data-efficient as promised?
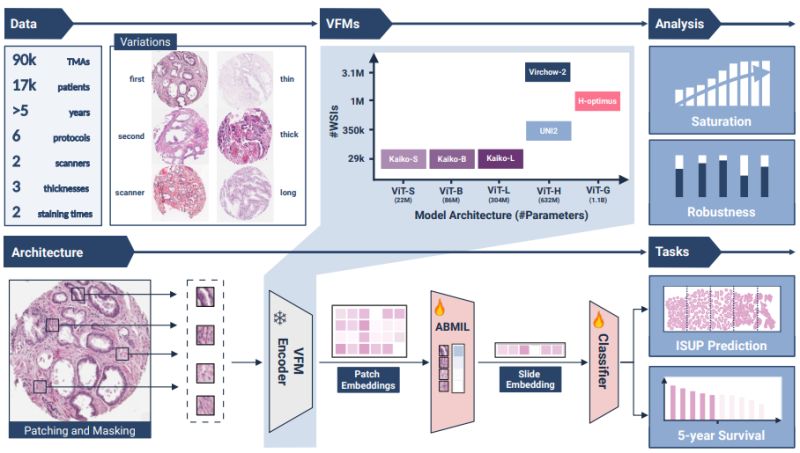
A preprint by 𝘼𝙣𝙟𝙖 𝙒𝙞𝙩𝙩𝙚 𝙚𝙩 𝙖𝙡. rigorously evaluated six VFMs on a protocol-variant prostate cancer dataset comprising over 37,000 spot images. The authors introduced six controlled domain shifts—including variations in staining duration, section thickness, scanner type, and sampling location—to test the models on clinically relevant tasks like ISUP grading and 5-year relapse prediction.
The results reveal some critical limitations in the current generation of models:
• 𝙏𝙝𝙚 𝙄𝙢𝙥𝙤𝙧𝙩𝙖𝙣𝙘𝙚 𝙊𝙛 𝘿𝙚𝙘𝙤𝙙𝙚𝙧 𝘿𝙚𝙨𝙞𝙜𝙣: The authors found that "downstream performance depends strongly on the chosen decoder architecture". While "simple probing approaches such as KNN, which are commonly used in the evaluation of foundation models, were insufficient for clinically relevant tasks", decoder-based approaches proved to be essential.
• 𝙏𝙝𝙚 𝙈𝙮𝙩𝙝 𝙊𝙛 𝘿𝙖𝙩𝙖 𝙀𝙛𝙛𝙞𝙘𝙞𝙚𝙣𝙘𝙮: One of the primary appeals of foundation models is their presumed ability to perform well with very few labeled examples. However, this study demonstrated that "the presumed data
efficiency of VFMs did not hold: stable decoder performance typically required more than 1000 training samples."
• 𝙑𝙪𝙡𝙣𝙚𝙧𝙖𝙗𝙞𝙡𝙞𝙩𝙮 𝙏𝙤 𝘿𝙤𝙢𝙖𝙞𝙣 𝙎𝙝𝙞𝙛𝙩𝙨: Even with massive pre-training, "none of the models demonstrated sufficient robust generalization under protocol-level domain shifts." The models exhibited performance reductions of 4 to 13% in key tasks when faced with standard laboratory variations.
𝙏𝙝𝙚 𝙏𝙖𝙠𝙚𝙖𝙬𝙖𝙮: While larger foundation models exhibit better peak accuracy and somewhat greater robustness, they do not fully address the critical issues of data efficiency and domain shift. To build truly reliable clinical tools, the field still needs substantial labeled datasets, robust decoder architectures, and improved domain adaptation methods.
|
|
|
|
|
